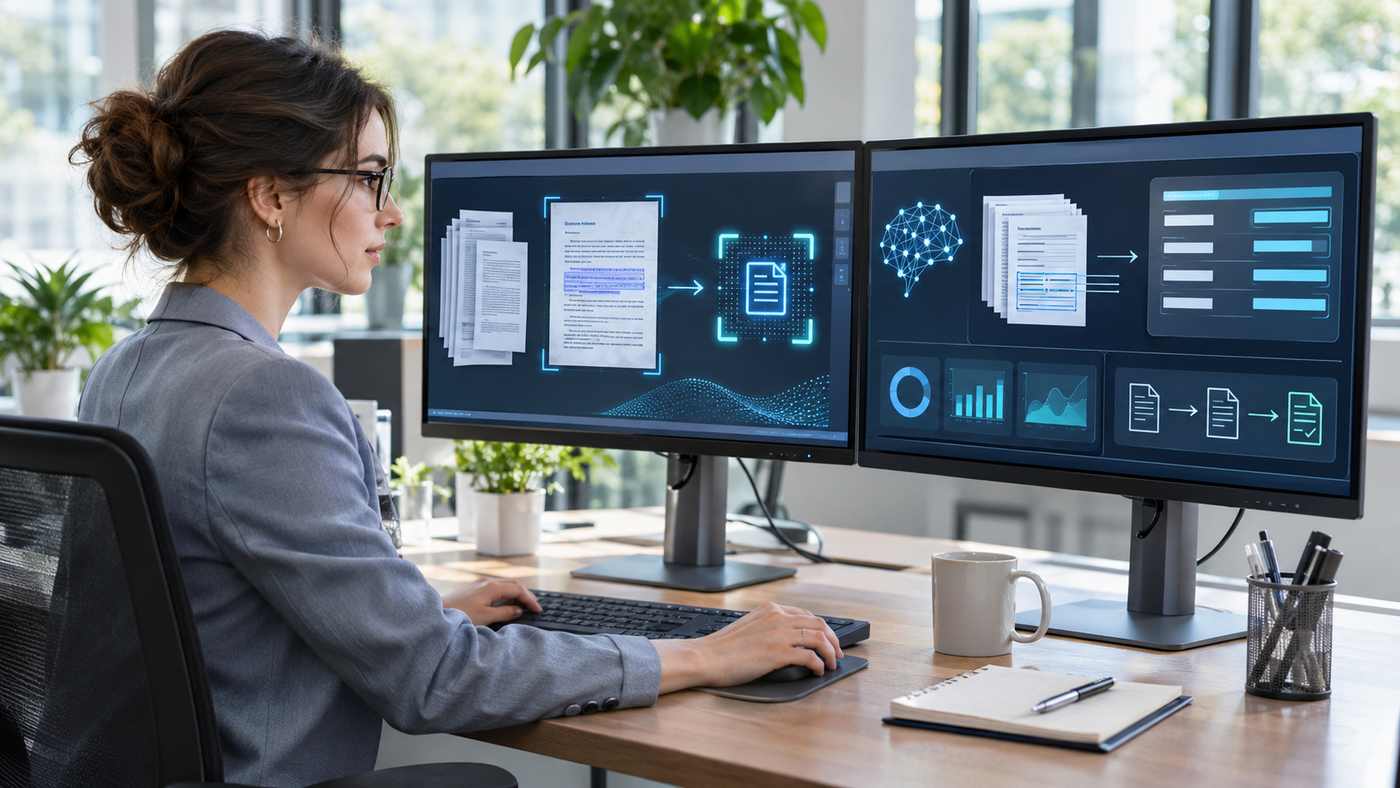
IT departments manage growing volumes of digital documents alongside business software, cloud platforms, and enterprise information systems. Invoices, contracts, forms, and scanned records contain information that businesses need for daily operations. Extracting that information accurately helps organizations automate administrative tasks, update databases, and reduce manual data entry.
Optical character recognition (OCR) has supported document digitization for decades. However, changing document formats and increasingly connected software systems have created demand for more advanced solutions. Technologies such as AI document processing combine text recognition, machine learning, document classification, and automated validation to organize information for business applications.
Why Traditional OCR Still Matters in Business Software
Traditional OCR converts printed or scanned text into machine-readable characters. It allows organizations to search archived documents, digitize paper records, and transfer information into software systems.
The open-source Tesseract OCR engine demonstrates this established approach. Its documentation explains how developers can extract printed text from images through command-line tools or application programming interfaces.
OCR works particularly well when documents follow predictable layouts. Standard application forms, printed receipts, and fixed-format reports can be processed using predefined extraction rules.
However, recognizing text does not automatically explain its meaning. A conventional OCR system might identify several dates on an invoice without knowing which represents the payment deadline.
What Changes When Artificial Intelligence Enters Document Processing?
AI-powered systems extend text recognition through machine learning and document analysis. They can identify document categories, detect relationships between fields, and convert extracted information into structured records.
Google Cloud explains that its Document AI Form Parser identifies key-value pairs, tables, selection marks, and common fields. Custom extraction models can also target information within specialized documents.
These capabilities become useful when organizations receive invoices from different suppliers or contracts with changing structures. However, intelligent extraction still requires testing, monitoring, and human review when accuracy is uncertain.
Accuracy: Recognizing Words vs. Understanding Information
Structured Documents Favor Predictable Extraction
Traditional OCR combined with fixed extraction rules can perform effectively when information appears consistently. A standardized form with clearly positioned fields presents fewer processing challenges.
For these documents, introducing advanced machine learning may offer limited additional value. A carefully configured conventional system might already meet operational requirements.
Complex Documents Create Different Challenges
Semi-structured invoices and unstructured contracts require greater flexibility. Supplier names, payment terms, and totals may appear in different locations.
Amazon Web Services documents how Amazon Textract can identify forms, tables, and relationships between extracted fields. However, its technical guidance also warns that merged cells and unusual table layouts can produce inconsistent results.
AI-based extraction can improve field identification in variable documents, but performance depends on document quality, model capabilities, and validation procedures. Similar concerns about reliability appear in discussions of the limitations of AI detection algorithms, where statistical patterns and machine learning predictions do not always produce accurate conclusions.
Although document extraction and AI-generated content detection serve different purposes, both demonstrate why automated results should be evaluated carefully before organizations rely on them.
Document Compatibility: Which Technology Handles More Formats?
Traditional OCR generally processes images or scanned document pages. Some implementations require additional software to convert files into compatible formats.
For example, Tesseract documentation identifies supported image formats, including PNG, JPEG, and TIFF. Its core engine does not directly read PDF files without conversion.
Modern intelligent document platforms may accept broader file categories. Microsoft documents support for PDFs, common image formats, and selected Microsoft Office files through its Document Intelligence layout model.
Nevertheless, broader compatibility does not guarantee accurate extraction. Poor scanning quality, unusual formatting, and damaged pages can affect either approach.
Automation: Fixed Rules or Context-Aware Workflows?
Conventional OCR systems typically rely on templates, coordinates, and predefined rules to identify important information.
This approach supports repeatable processes. However, a redesigned supplier invoice might require developers to update extraction templates manually.
AI-enabled systems can classify documents and identify fields using learned patterns. An automated workflow might recognize an invoice, extract its payment details, validate totals, and forward the record for approval.
Google Cloud provides document classification and extraction processors for these workflows. Their usefulness depends on suitable configuration and reliable validation rules.
Software Integration: Does Either Approach Have an Advantage?
Both technologies can connect with enterprise resource planning systems, customer relationship management platforms, databases, and cloud applications.
Traditional OCR often needs additional software to transform recognized text into structured fields. Developers can then use scripts, middleware, or APIs to transfer records.
Intelligent platforms may provide structured extraction results through APIs. Microsoft documents REST interfaces and software development kits for integrating Document Intelligence with business applications.
Integration quality ultimately depends on data formats, authentication requirements, error handling, and compatibility with existing infrastructure.
Implementation Costs: Simple Setup vs. Long-Term Maintenance
Traditional OCR can involve lower initial software costs, especially when organizations use open-source engines. However, custom extraction rules, document conversion, and manual corrections still require resources.
AI-powered services introduce different expenses. These may include usage-based processing charges, model configuration, integration development, and ongoing performance monitoring.
Cost comparisons should therefore consider:
- Software licensing and processing fees.
- Development and integration requirements.
- Human verification and correction time.
- Maintenance when document layouts change.
- Infrastructure and data protection expenses.
The less expensive option depends on total operating costs rather than software pricing alone.
Scalability and Security: Different Technologies, Shared Responsibilities
Both OCR and intelligent extraction systems can process large document volumes through suitable infrastructure and automation.
Cloud services may simplify capacity management, while locally deployed systems can provide greater direct control over processing environments.
Security remains essential regardless of technology. National Institute of Standards and Technology (NIST) SP 800-53 describes controls covering access management, audit logging, and information protection.
For AI-enabled systems, the NIST AI Risk Management Framework also emphasizes continuous evaluation, governance, and performance monitoring.
Organizations should assess encryption, access permissions, data retention, vendor practices, and applicable privacy obligations before deployment.
Which Approach Makes Sense for Modern IT Teams?
Traditional OCR remains practical for standardized records, predictable layouts, and straightforward digitization projects. Its established tools and rule-based processes can provide sufficient performance without unnecessary complexity.
AI-enabled extraction offers greater flexibility for mixed document collections, changing formats, and workflows requiring contextual information. Yet its additional capabilities introduce implementation and oversight responsibilities.
A hybrid approach may also work. Organizations can retain conventional recognition for simple documents while directing complex records through intelligent extraction and human verification.
Conclusion
Choosing between traditional OCR and AI-powered document processing requires careful evaluation of business requirements. Document complexity, extraction accuracy, integration needs, IT resources, security expectations, and long-term costs should guide the decision.
Newer technology is not automatically the better solution. The most effective system is one that delivers reliable information, supports existing software, and remains manageable as business workflows evolve.